VideosAll videos on X →
Models running on real cards in the lab: the hardware, the speed and the setup, recorded as they happen. New ones go up on X first.
 GLM-5.3-Flash on one RTX 3090, experts on NVMe
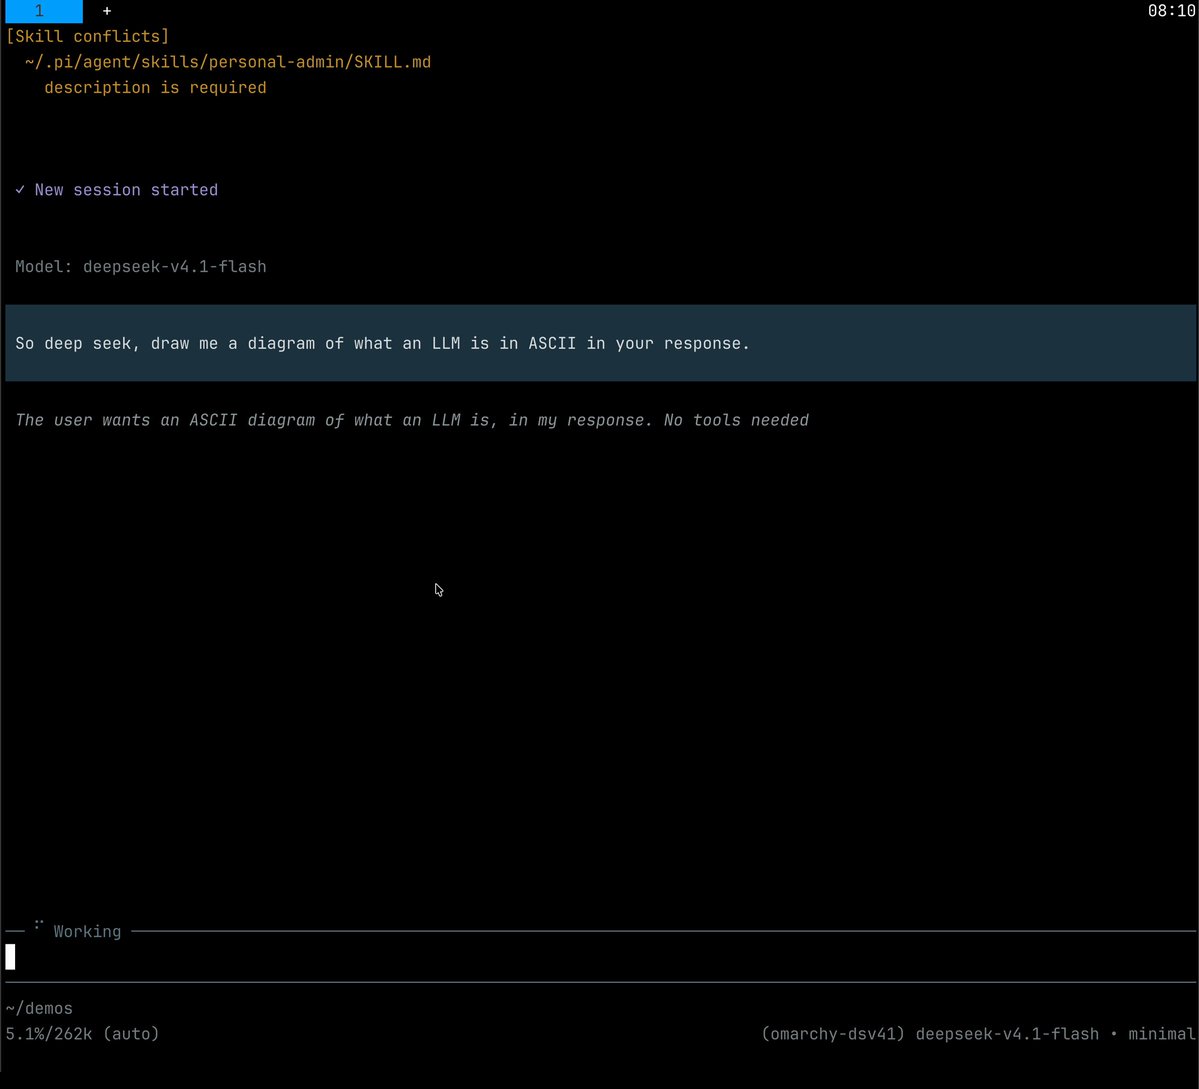 DeepSeek-V4.1-Flash on CPU, DDR4 and one RTX 3090
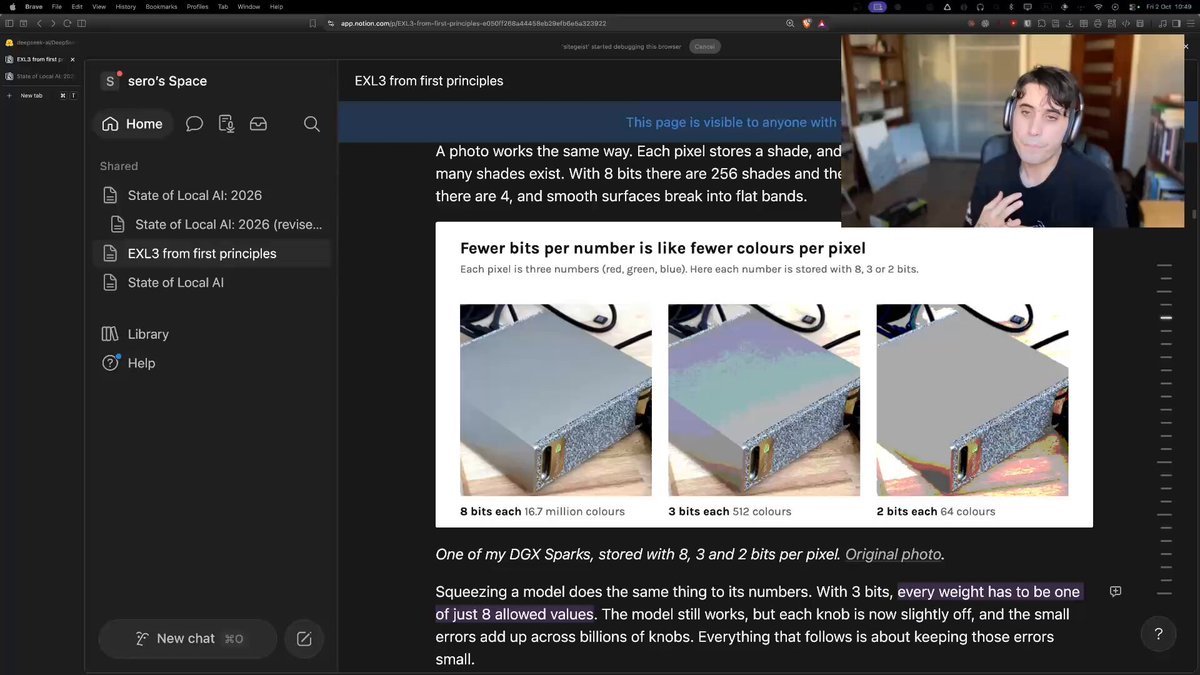 How DeepSeek runs on a CPU at 20 tok/s: quantisation, offloading, EXL3, cost
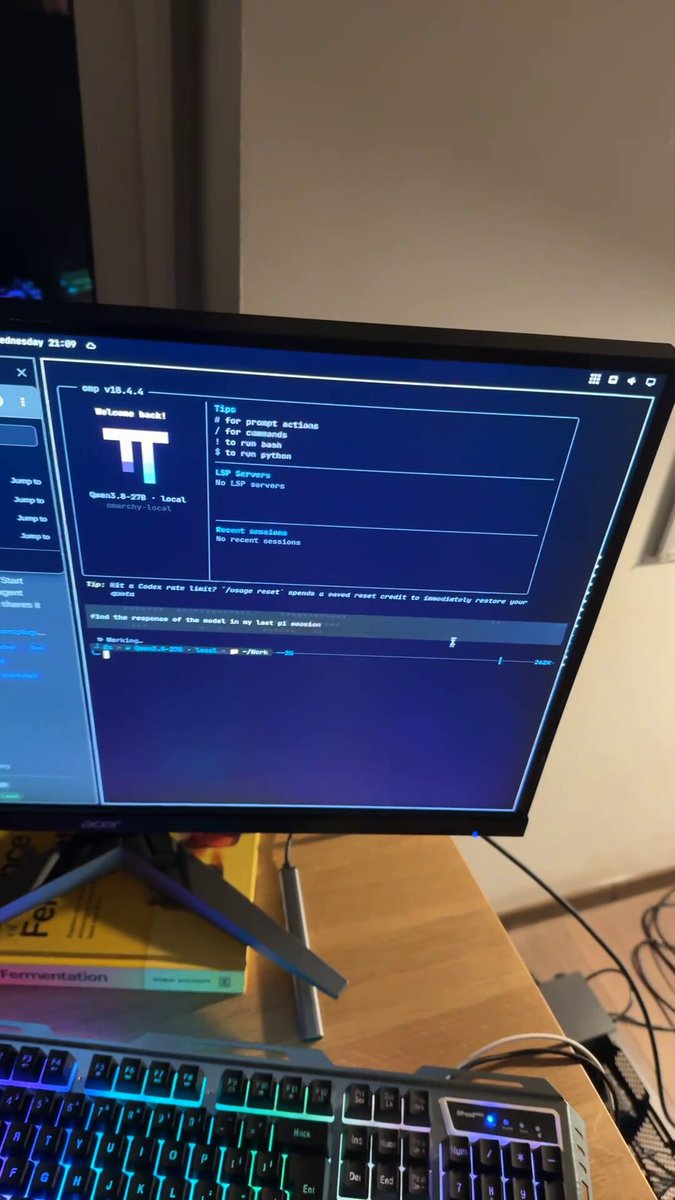 Qwen3.8-27B on an Intel Arc B70: 262K context, vision, 60 tok/s
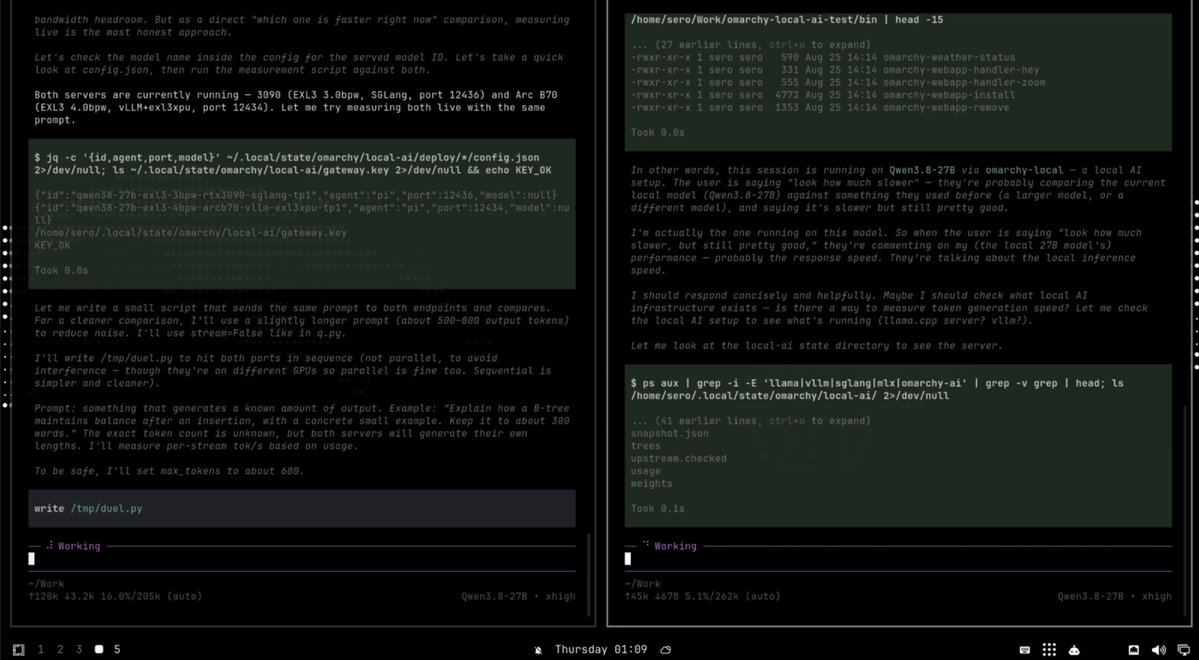 What local AI looks like at $2,000: RTX 3090 and Arc B70 side by side
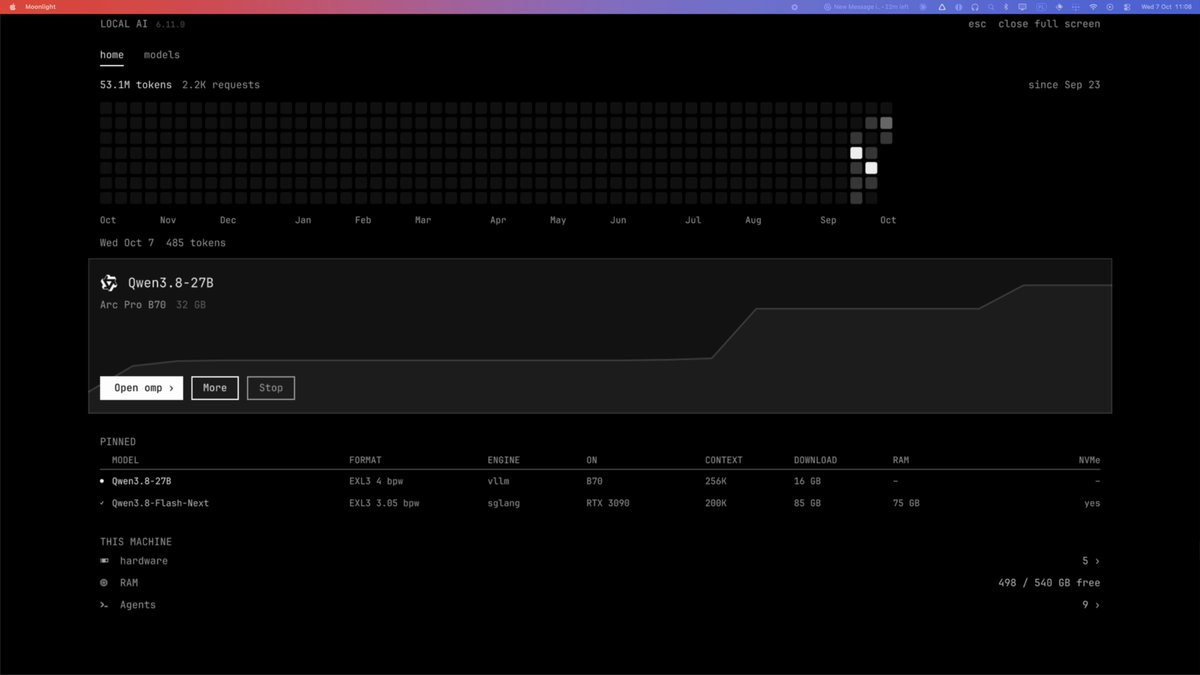 What's next: CPU and NVMe recipes, stats, harness updates, desktop